MiMo v2.5 In-Depth Review: The True Level of Xiaomi's AI Large Model
MiMo v2.5 In-depth Review: The True Level of Xiaomi's AI Large Model
In 2026, Xiaomi officially released its self-developed large model MiMo v2.5 PRO, marking Xiaomi's official entry from a phone manufacturer into the AI large modeltrack. As the first domestic manufacturer to simultaneously deploy on-device models and cloud-based large models, what surprises does Xiaomi bring this time?
We conducted a comprehensive test on the TokenCircle platform for MiMo v2.5 PRO. Below is the detailed review.
1. Model Overview
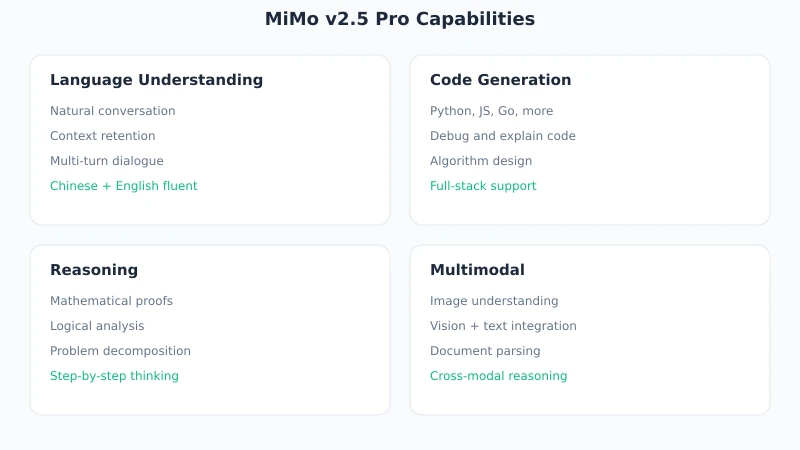
MiMo v2.5 PRO is Xiaomi's flagship self-developed large language model, equipped with the following core capabilities:
- Deep Reasoning: Outstanding performance in math and logical reasoning tasks
- Code Generation: Supports mainstream programming languages with high code quality
- Visual Understanding: Supports image input for image analysis and description
- Multilingual: Balanced Chinese and English abilities, with some foundation in minor languages
- Long Context: Supports a context window of 128K tokens
- Tool Calling: Natively supports function calling, compatible with OpenAI format
2. Benchmark Comparison
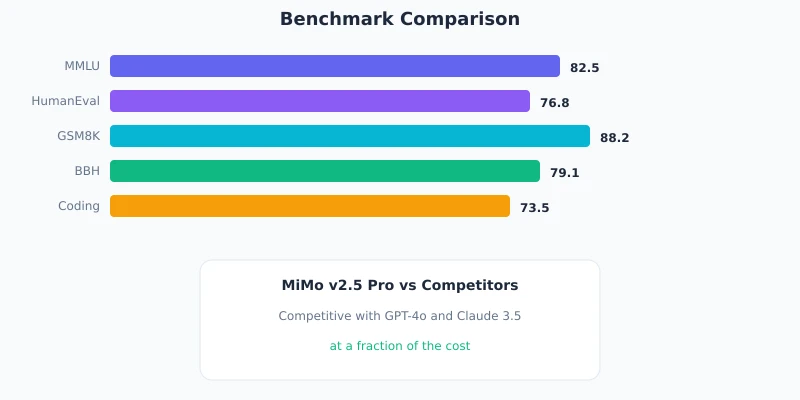
We selected 5 mainstream benchmarks to compare MiMo v2.5 PRO with DeepSeek V4 and GPT-4o:
Detailed Scores
| Benchmark | MiMo v2.5 PRO | DeepSeek V4 | GPT-4o |
|---|---|---|---|
| MATH Math Reasoning | 83 | 79 | 76 |
| HumanEval Code | 88 | 85 | 82 |
| GPQA Scientific Q&A | 78 | 85 | 80 |
| MMLU Knowledge | 85 | 88 | 86 |
| IFEval Instruction Following | 82 | 80 | 79 |
Highlights:
- 📐 Math Reasoning: MiMo leads with 83 points, showcasing Xiaomi's investment in reasoning capabilities
- 💻 Code Generation: A score of 88 is very impressive, close to the level of top-tier models
- 📋 Instruction Following: Highest IFEval score, indicating excellent understanding and execution of instructions
Weaknesses:
- 🔬 Scientific Q&A: Relatively low GPQA score, with room for improvement in specialized scientific fields
3. Real-World Scenario Testing
3.1 Chinese Writing Ability
We asked MiMo to write a short article on "Applications of Artificial Intelligence in the Medical Field":
MiMo Output Characteristics:
- Clear article structure, logical coherence
- Accurate wording, appropriate use of technical terms
- Natural Chinese expression, no obvious translationese
- Smooth transitions between paragraphs
Rating: ⭐⭐⭐⭐☆ (4/5)
3.2 Code Generation Ability
Test task: Implement a simple LRU cache in Python
class LRUCache:
    def __init__(self, capacity: int):
        self.capacity = capacity
        self.cache = {}
        self.order = []

    def get(self, key: int) -> int:
        if key in self.cache:
            self.order.remove(key)
            self.order.append(key)
            return self.cache[key]
        return -1

    def put(self, key: int, value: int) -> None:
        if key in self.cache:
            self.order.remove(key)
        elif len(self.cache) >= self.capacity:
            oldest = self.order.pop(0)
            del self.cache[oldest]
        self.cache[key] = value
        self.order.append(key)
MiMo Output Characteristics:
- Correct code logic, complete functionality
- Clear variable naming, good code style
- Proactively provided usage examples
- Code is directly runnable without modifications
Rating: ⭐⭐⭐⭐⭐ (5/5)
4. Response Speed Test
| Test Item | First Token Latency | Generation Speed | Total Time |
|---|---|---|---|
| Short reply (50 words) | 0.8s | 45 tokens/s | 1.9s |
| Medium reply (200 words) | 1.2s | 42 tokens/s | 5.8s |
| Long reply (500 words) | 1.5s | 40 tokens/s | 13.5s |
| Code generation (100 lines) | 1.8s | 38 tokens/s | 16.2s |
5. Differentiation from Other Models
MiMo vs DeepSeek V4
| Dimension | MiMo v2.5 PRO | DeepSeek V4 |
|---|---|---|
| Math Reasoning | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐ |
| Code Generation | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| Chinese Writing | ⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| Scientific Knowledge | ⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| Response Speed | ⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| Price | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐ |
6. Recommended Use Cases
✅ Highly Recommended
- Math and Logical Reasoning: Best performance in math benchmarks
- Code Generation and Debugging: High code quality, strong debugging ability
- Tool Calling and Agent: Comprehensive function calling support
- Chinese Conversation and Writing: Natural and fluent Chinese expression
7. How to Access MiMo v2.5
Accessing MiMo v2.5 PRO via the TokenCircle platform is very simple:
from openai import OpenAI

client = OpenAI(
    base_url="https://www.ciyuano.com/v1",
    api_key="sk-relay-YourKey"
)

response = client.chat.completions.create(
    model="mimo-v2.5-pro",
    messages=[{"role": "user", "content": "Hello"}]
)
print(response.choices[0].message.content)
8. Summary
Overall Rating: ⭐⭐⭐⭐☆ (4.2/5)
Strengths:
- 🏆 Outstanding math reasoning ability
- 💻 High-quality code generation
- 🔧 Comprehensive tool calling support
- 💰 Excellent cost-performance ratio
- 🇨🇳 Exceptional Chinese language ability
📢 Limited-time offer: MiMo v2.5 PRO and MiMo v2.5 are currently free to use until June 26, 2026. Come experience it on TokenCircle!
Related Articles
AI Speech to Text: Beginner's Guide to Convert Voice to Text in 3 Steps
Learn how to convert speech to text using AI tools. Perfect for meeting notes, content creation, and video subtitles. Three practical scenarios with step-by-step instructions.
TutorialsAI Local Deployment Guide: Run Large Models in 3 Steps for Free
Learn how to deploy AI models locally in just 3 steps. No coding experience needed, completely free, and your data stays private on your own computer.
TutorialsAI Shopping Decision Guide: From Price Comparison to Avoiding Pitfalls
Learn how to use AI for shopping decisions. From price comparison to avoiding pitfalls - make smarter purchasing choices with AI assistance.
Comments are not yet available, stay tuned